Getting the length of a string seems simple and is something we do in our code every day. Limiting the length of a string is also extremely common in both frontend and backend code. But both of those actions – especially length limiting – hide a lot of complexity, bug-risk, and even vulnerability danger. In this post, we’re going to examine string length limiting deeply enough to help us fully grok what it means when we do it and how best to do it… and discover that the best still isn’t great.
A TL;DR misses the “fully grok” part, but not everyone has time to read everything, so here are the key takeaways:
- Be aware that there are different ways of measuring string length.
- Really understand how your programming language stores strings in memory, exposes them to you, and determines string length.
- Make an intentional decision about how you’re going to count characters when limiting string length.
- Look carefully at how the “max length” features provided by your language (framework, etc.) actually work. There’s a very good chance that they do not match the limiting method you chose.
- Make sure you use that same counting method across all the layers of your architecture.
- Probably limit by counting Unicode code points. (Like Google recommends.) NFC-normalize strings that will be compared or used as identifiers, and consider it for counts shown to users.
With that out of the way, let’s start our investigation by looking at some of our familiar string length functions:
| “a” | “字” | “🔤” | “👨👩👧👦” | “र्स्प” | “x̴͙̹̬̑̓͝͝” | ||
|---|---|---|---|---|---|---|---|
| Go | len(string) | 1 | 3 | 4 | 25 | 15 | 17 |
| JavaScript | String.length | 1 | 1 | 2 | 11 | 5 | 9 |
| Python 3 | len(str) | 1 | 1 | 1 | 7 | 5 | 9 |
| Swift | String.count | 1 | 1 | 1 | 1 | 1 | 1 |
Those four measurements of string length are exemplars of the approaches common to most programming languages: UTF-8 bytes, UTF-16 code units, Unicode code points, and grapheme clusters.
## Character encodings and terminology
There are good explanations of this stuff elsewhere, but let’s try to quickly get a handle on the concepts we need to go further. (Feel free to skip anything you’re already comfortable with.)
First, a working definition of a “character”: This is the human conceptual ideal of the smallest building block of most written languages1: a letter, an emoji, an ideograph, a punctuation mark, a symbol, a grapheme. Later on we’ll also think of a character as “if a user types this, they expect a ‘character count’ to increase by 1”. All of the examples in the above table probably look like “a character” to you.
(We’re going to avoid using this term lightly, in favour of technical correctness, to avoid confusion. So I’m never going to say “Unicode character”.)
### Unicode
Unicode is humanity’s attempt to list all possible characters, plus a whole lot more: control characters, non-printable characters, fragments that can be combined to form characters, and so on.
Each entry in the Unicode space is called a “code point” and is represented with a 32-bit unsigned integer, though only 21 bits are actually needed: the code space runs from U+0000 to U+10FFFF (about 1.1 million possible values) and only about 150,000 of those values have been assigned. You might also see the term “Unicode scalar values” – these are basically the same as code points, but exclude the reserved “surrogate pair” range.
Examples (character: code, decimal)
Strictly speaking, a “Unicode code point” is an abstract concept, with a numerical value assigned to each character. There are 3 common concrete schemes for encoding those code points: UTF-8, UTF-16, and UTF-32. “UTF-32” is a direct representation: 32 bits to encode the 32 bits, with endian variants. I’m going to prefer just saying “Unicode code point” for clarity. We’ll discuss UTF-8 and UTF-16 at length below.
Note that in Go, a Unicode code point is typically called a “rune”. (Go seems to have introduced the term for the sake of brevity2. I certainly appreciate that, but I’m going to stick with universal terms here.)
### Grapheme cluster
Some Unicode code points can be combined and rendered into a single visual character; we call this a grapheme cluster (or extended grapheme cluster).
We’ll go through some examples, to help illuminate the complexity.
- “👨👩👧👦”: composed of 7 code points
The family emoji is an example of a “zero-width joiner (ZWJ) sequence”.
Not all possible combinations of emoji (or code points generally) can be combined in such a way to create a single grapheme cluster character. The Unicode consortium publishes all defined emoji, including multi-code-point compounds.
Whether and how an emoji is rendered depends on the platform you’re viewing it on. For example, here is what the family emoji looks like in Brave browser on Windows – 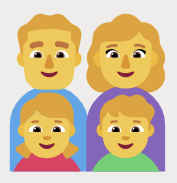 – versus on Android –
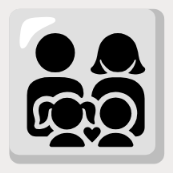 .
And rendering can change over time. In 2016, with the Windows 10 Anniversary Update, Microsoft introduced the “ninjacat” ZWJ sequence emoji, combining the “cat face” and “bust in silhouette” emoji. It wasn’t supported by any other platform. In 2021, Microsoft removed support for it and now it renders as two separate emoji.
The family emoji itself has gone through some major changes. (Maybe it was even removed from iOS at some point, but it seems to render fine now.)
There are also “combining marks” that are accents or other fragments that don’t require a ZWJ between the code points.
This is an example of a grapheme cluster that can instead be represented with a single code point: U+00E9 is “Latin Small Letter E With Acute” and is visually identical to the above, decomposed cluster. (See “Unicode normalization”, below.)
Use of characters formed by grapheme clusters (that can’t be normalized away) are extremely uncommon in languages that use European and East Asian scripts, but fairly common in South Asian scripts, like Hindi where ~25% of characters involve a combining mark.
- “र्स्प”: composed of 5 code points
And then there’s Zalgo text, which abuses combining marks in c̴͚͉͔̓̑͂͜r̷̙̎̎̿͊a̵̜͍̱̋̕z̷̭̰͉͊̎́͒y̵̺̿̔ ways:
- “x̴͙̹̬̑̓͝͝”: composed of 9 code points
- ordinary letter “x”
- “̴”, U+0334, “Combining Tilde Overlay”
- “͝”, U+035D, “Combining Double Breve”
- “̑”, U+0311, “Combining Inverted Breve”
- “͝”, U+035D, “Combining Double Breve” (again)
- “̓”, U+0343, “Combining Greek Koronis”
- “͙”, U+0359, “Combining Asterisk Below”
- “̹”, U+0339, “Combining Right Half Ring Below”
- “̬”, U+032C, “Combining Caron Below”
As far as I can tell, there is no limit on the number of code points that can contribute to a single grapheme cluster “character”. We’ll certainly keep that in mind when we think about how to limit string length, below.
(You will sometimes see the word “segmentation” used when talking about extracting grapheme clusters from a string. It generically refers to breaking a string into defined pieces; for example, the JavaScript Intl.Segmenter API can break a string into graphemes, words, or sentences.)
### Unicode normalization
Unicode normalization has two functional axes: composition/decomposition and compatibility simplification, resulting in four modes with standard names. The “NF” is “normalization form”; “C” is “canonical composition”, “D” is “canonical decomposition”; “K” is “compatibility simplification”. Which gives us:
| No Simplification | Simplification | |
|---|---|---|
| Composition | NFC | NFKC |
| Decomposition | NFD | NFKD |
Composition canonicalization will combine the two-code-point grapheme cluster form of “é” (U+0065 + U+0301) into the single-code-point form “é” (U+00E9); and similar for other grapheme clusters for which an equivalent single code point exists (and leaves sequences with no single-code-point equivalent as separate code points; e.g., Zalgo text keeps nearly all of its combining marks, though they may be reordered. There are a few exceptions where NFC decomposes instead; see “Normalization concerns”, below.) Decomposition canonicalization will do the opposite: single-code-point characters will be decomposed into multi-code-point grapheme clusters (this includes decomposing Korean Hangul into jamo phonetic components).
Compatibility simplification converts some fancy characters into more ordinary ones. For example, “ℍ” (U+210D) and “ℌ” (U+210C) become plain Latin “H”; superscript “²” becomes plain number “2”; “ffi” (ligature) becomes “ffi”. The non-simplifying forms don’t replace such characters. (Note that ordinary diacritics aren’t removed – “é” keeps its accent.) Unlike canonicalization, simplification is not reversible.
NFC is good for keeping a string as compact as possible while ensuring greater consistency.
NFKC is good if you want the string to be searchable or otherwise comparable using equivalent characters (like matching “ℍ𝔼𝕃𝕃𝕆” when searching for “HELLO”).
The decomposition forms (with additional processing) are useful for stripping out all accents; e.g., if you want plain ASCII for searching or for use in filenames.
Note that the output of normalization may change between versions of Unicode. See the Unicode Versions section, below, for discussion of how that kind of thing can go wrong.
### UTF-8
UTF-8 encodes code points into a sequence of 1, 2, 3, or 4 one-byte code units. It has the very nice property of providing a compact encoding for most string data; in particular, all ASCII printable characters fit in one byte, with the same ASCII numeric value (e.g., if you open an ASCII view of a UTF-8 encoded source file, you can probably read it just fine). It is by far the most common encoding to find serialized to disk or on the wire (in recent years).
Note that there is overhead in the design3, so you don’t get the full 8*bytes number of bits to represent code points. Here’s how it breaks down:
- 1 byte: 7 bits
- 2 bytes: 11 bits
- 3 bytes: 16 bits
- 4 bytes: 21 bits
### UTF-16
UTF-16 doesn’t often get used on the wire or on disk, but many programming languages and OSes use it in-memory. The reason is that some platforms and languages originally supported UCS-2, which is the old 2-byte Unicode standard. When Unicode grew beyond 16 bits (to 21 bits), UTF-16 was created. It uses 1 or 2 two-byte code units in a code point sequence. Sequences of a single code unit are identical to and backwards compatible with UCS-2, making the transition for UCS-2 platforms reasonably easy.
(Two UTF-16 code units making a code point is called a surrogate pair. Unicode reserves a range of code points, U+D800 to U+DFFF, that never represent characters on their own; UTF-16 uses values from that range to indicate when a second UTF-16 code unit is used in the code point sequence.)
UTF-16 has the nice property that the entire “Basic Multilingual Plane (BMP)” fits in a single UTF-16 code unit. That’s the “majority of the common characters used in the major languages of the world” (but doesn’t include emoji, notably). The downside is that it takes twice as much space to represent ASCII characters.
(Note that it takes three UTF-8 bytes to fit the entire BMP.)
### Other encodings
We’re not going to get into code pages, WTF-8, CESU, etc. They’re not relevant to the task at hand (and I don’t know enough to say anything useful).
## String lengths
Now that we understand character encoding better, let’s revisit the table above.
| Encoding Count | “a” | “字” | “🔤” | “👨👩👧👦” | “र्स्प” | “x̴͙̹̬̑̓͝͝” |
|---|---|---|---|---|---|---|
| UTF-8 code units | 1 | 3 | 4 | 25 | 15 | 17 |
| UTF-16 code units | 1 | 1 | 2 | 11 | 5 | 9 |
| Unicode code points | 1 | 1 | 1 | 7 | 5 | 9 |
| Grapheme clusters | 1 | 1 | 1 | 1 | 1 | 1 |
So, different programming languages (and functions within a language) give us different methods of counting. Some examples4:
- UTF-8: Go, Rust, C++’s
std::u8string, Haskell’sTextv2 - UTF-16: Java/Android, JavaScript (and TypeScript), Dart, C#/.NET (and Windows), Objective-C/iOS (
NSString), Haskell’sTextv1. - Unicode: Python 3, Ruby, PostgreSQL, Haskell’s
Char - Grapheme cluster: Swift’s
String.count, Elixir’sString.length, Raku
Note that many (probably all) languages provide ways of converting between encodings and counting “length” in those other encodings; the above are just defaults. There might also be a difference between which encoding is used in-memory versus which is presented as the main programming interface to access those strings.
To understand how our programming languages of choice deal with string length, it’s worth taking a step back and thinking about what a string is. The definition of “string” that many of us would give is something like “a bunch of characters”. But we’ve seen now that “character” only has an abstract meaning, so it’s not enough to help us when we use a string type. We need to know and keep in mind two things:
- the underlying in-memory representation of strings, and
- the view into that representation presented to us.
A few examples:
Go’s string type is really an array of bytes. The intention is that those bytes hold UTF-8 code units, but there’s no guarantee of UTF-8 sequence validity. len(string) gives the byte length of the string. Indexing a string (s[i]) gives you a byte/code unit, but iterating over it with range gives you a Unicode code point/rune at each step. Go provides unicode/utf8.RuneCountInString to get the code point count. It also has the unicode/utf16 package for converting between runes (code points) and UTF-16 code units. It has no built-in support for grapheme cluster segmentation.
JavaScript’s string type is a set of UTF-16 code units and string.length gives you a count of those code units. [...string] gives an array of Unicode code points. TextEncoder converts to UTF-8. Intl.Segmenter provides access to grapheme clusters.
Swift’s underlying representation used to be UTF-16 but has been UTF-8 since 2019. Its Character type holds a single grapheme cluster and String.count returns grapheme cluster count. To access encodings, it provides String.UTF8View, String.UTF16View, and String.UnicodeScalarView.5
Having a deeper understanding of how strings work under the hood will help prevent the confusion of discovering that a single emoji has a length of 7, and the bugs that can follow from that confusion.
### Limiting and Consistency
We finally get to the real point of this post!
Because there are 4 different ways to encode characters, there are 4 different ways to count string length. Because there are 4 different ways to count string length, there are (at least) 4 different ways to limit the length of a string.
That makes it really easy to be inconsistent across levels of your architecture, leading to bugs and bad user experience. They can be easy to miss in testing, since certain characters and character combinations might be needed to reveal them.
Here are a few length limiters that I was looking at when I decided I needed to write this post:
- Go’s validator package (not stdlib, but popular): The
maxandminlimiters count Unicode code points (“runes” in Go-speak). - If you create a column constraint with PostgreSQL’s
char_length(), it’ll limit by Unicode code points (by default). - The HTML attribute
maxlengthoninputortextareaelements limits by UTF-16 code units. (Except… I have found that IE limits by Unicode code points instead.) - React Native’s
TextInput.maxLengthlimits by UTF-16 code units. This is because on iOS it usesNSString.lengthand on Android it usesInputFilter.LengthFilter. - Flutter’s
TextField.maxLengthlimits by grapheme clusters (“user-perceived characters”, via thecharacterspackage), even though Dart’s ownString.lengthcounts UTF-16 code units. That makes it the only limiter here whose count doesn’t bound the size of the input: a single Zalgo “character” with hundreds of combining marks counts as 1. (See “Grapheme clusters”, below.)
Rant: It’s really annoying that the method of counting length often isn’t immediately apparent in the documentation. I should not have had to dig into React Native source code to get the answer. (And this isn’t just an RN problem.)
Inconsistencies can arise between frontend clients and backend API servers, between API and database, between different client implementations, between different servers accessing the same database, and so on. Let’s look at some problems that inconsistent length-limiting can lead to.
If the frontend allows longer input than the backend (perhaps by the frontend allowing 100 Unicode code points while the backend allows 100 UTF-8 or UTF-16 code units), the frontend may indicate that the user’s input is valid just to have it rejected by the backend.
If the frontend has a shorter input limit than the backend, the user will be unnecessarily restricted. In the case of something like a username, if the account was created in a frontend with consistent counting and then the user tries to login on a client with too-short counting, they might be unable to. One can imagine other too-long data might cause a frontend to freak out: assertion failure, refuse to display it, force the user to change it, etc.
Similar problems will occur with length-restrictions at other levels, such as between backend(s) and database.
Be intentional and consistent with how you limit string length. Don’t just blindly use the default on whatever OS you happen to be on and whatever language you happen to be programming in.
Problem severity reality check: Probably allowing this kind of inconsistency won’t result in a fatal bug. Probably it won’t render your UI unusable or crash your server. Probably it won’t introduce an ugly security vulnerability. Most users aren’t going to create usernames that are maximum length. Most users won’t use characters beyond the BMP in their username (although expect emoji elsewhere). You could probably go your whole career not paying any attention to this and probably not get bitten hard by it. But a) you’re curious, and b) you want to limit the margins on “most” and “probably”, so let’s figure out how to do this better.
### How to limit?
This is the question that really prompted me to write this post: What’s the best way to limit string length input?
Let’s go through each encoding type again and consider them as candidates for limiting. We’ll be thinking about it from both UI and API points of view. Keep in mind that the way you’re “limiting” is often different on the frontend versus backend: on the backend, you’re probably just rejecting the input (HTTP 400); on the frontend, you’re either a) showing the user they’ve typed beyond the limit and telling them to fix it, or b) preventing them typing beyond the limit, or c) truncating the input.
Let’s also make explicit: Usually, the reason we want to limit count is because we want to limit size. We don’t want infinitely long usernames, chat messages, or even books. Even if we had no trouble displaying them, we can’t process and store them. Limiting by count rather than byte-size can be more humane, and we’ll keep this in mind as we consider approaches.
#### Grapheme clusters
Because they’re closest to representing what humans think of as a “character”, grapheme clusters seem like they should be the right thing to count. But they’re actually the worst because, again, there’s no limit on the number of code points in a grapheme cluster. Maybe you can use them to limit count, but you can’t use them to limit size. (At maximum “craziness”, zalgo.org adorns the letter “x” with 360 accents and whatnot – for 361 total code points. Swift’s String.count still, correctly, says that it’s one grapheme cluster.)
(Perhaps you could limit the number of code points per cluster, but you’d be breaking the Unicode spec and it’s probably a bad idea. For something along those lines, see the “Hybrid Counting” section below.)
Grapheme clusters also require additional processing and interpretation. This is more of a rendering problem (e.g., iPhones have had multiple crash bugs), but a complex code path during input validation (potentially before authentication, etc.) should give anyone pause.6
To a greater degree than the other options, operating at the grapheme cluster level is sensitive to differences between Unicode versions. For example, if a new grapheme cluster is added, a newer segmentation algorithm will count it as 1, while an older Unicode version may count it as the individual code points.
Not all programming languages have built-in grapheme cluster segmentation support. For example, Go has third-party packages, but no support in the stdlib or in golang.org/x/text. Dart’s comes from the characters package, which is published by the Dart team but isn’t part of the core library.
#### UTF-16 code units
If you’re starting from the frontend, there’s a good chance that UTF-16 will be your default choice. There are reasons why it’s not a good choice.
A danger in length-limiting by counting code units is that you inadvertently break a character by truncating some of the code units in a sequence. React Native’s iOS limiter suffered this for at least 5 years before fixing it. It looks like RN’s Android limiter avoids this (“If a surrogate pair is encountered at the boundary, it backs off by one character to avoid splitting the pair”).
Counting by anything except grapheme clusters means that your count can jump by more than one per “character”, which is not the worst thing ever, but obviously undesirable UX. There are two reasons for this jump-counting:
- Applies to UTF-8, UTF-16, Unicode code points: If the character is a multi-code-point grapheme cluster.
- Applies to UTF-8, UTF-16: Multiple code units are required to encode the code point.
The first reason can be somewhat mitigated by using NFC normalization with every keystroke – to the extent possible, that will reduce clusters down to single code points. (Introducing latency while typing is also bad UX! Make sure to test the timing and feel.) We discuss this point more in the Unicode section below.
The second reason can’t be mitigated for UTF-8 and UTF-16 – by design, they can require multiple code units per code point. However, it’s much less of a problem for UTF-16, since the whole Basic Multilingual Plane fits in one code unit, though it depends on the type of input expected – it’ll still be a two-count per emoji, at least.
I’m going to reiterate the caveat to that last point: the vast majority of commonly used characters are located in the BMP, and therefore fit in one UTF-16 code unit. Therefore, for the vast majority of commonly used characters, counting by UTF-16 code units is equivalent to counting by Unicode code points. The big exception to this is emoji.
Another big factor is that, while UTF-16 is quite commonly used in-memory, it’s very unusual for it to be serialized on the wire or to disk (UTF-8 is used most commonly, rarely UTF-32). Because “size on wire” and “size on disk” are things we care about when limiting, it feels strange to count by the one format that we know won’t be serialized. But let’s not overstate it: UTF-16 will still get us within about a factor of two of serialized size.
Using UTF-16 maximizes the amount of encoding conversion we’re going to have to do.
Additionally, in programming languages that primarily use UTF-8 or Unicode code points, UTF-16 seems to be a second-class citizen. For example, in Go, strings are UTF-8 and runes are what you get when you iterate over a string, but UTF-16 support requires the unicode/utf16 package. PostgreSQL doesn’t seem to support UTF-16 at all.
So, UTF-16 isn’t obviously terrible, but we can do better.
#### UTF-8 bytes
UTF-8 is a tempting choice because a) it’s a simple byte count, and b) it’s likely what we’re serializing to on the wire and on disk. It’s also very space-efficient for English text, although less so for other languages.
Counting characters by UTF-8 bytes in the UI is doomed to be confusing. For anything but plain English, the count will regularly increment by 2 or 3 or 4, and in ways that are not reasonable for a human to predict.
It’s important to note that there is a wide range in the significance of a string length limit to the UI/UX. On one end of the spectrum, there are very short fields with visible character counts; an obvious example is the old 140-character tweet limit, which users would stare at while trying to figure out creative contractions that wouldn’t obscure their point too much. On the other end is, say, a 10,000-character message board limit, where it’s not expected that many users will get near it; probably you don’t even bother showing the count, and you just hard-limit the input.
When there’s a very high limit, added for sanity and safety’s sake, it doesn’t really matter how you count characters. You’re not exposing the count to the user, and you probably don’t care if the limit is 10,000 UTF-32 code points, 20,000 UTF-16 code units, or 40,000 UTF-8 bytes.
But when the count is low and exposed to the user… UTF-8 counting is going to look weird.
#### Unicode code points
Argument from authority: Google’s API design guidance states that string size limits must be measured in Unicode code points, and that those strings should be NFC Unicode normalized.
I think this is approximately the best approach – not just for APIs, but also for UIs – but it’s not ideal.
Google’s guidance gives two reasons for normalizing, at two strengths: all values should be NFC normalized, to avoid discrepancies in size (code points and code units); unique identifiers must be, so that two visually identical strings can’t identify different resources. I think that’s the right split, and it’s worth being explicit about what normalization buys you:
- Equality. If a string is going to be compared, looked up, or checked for uniqueness (usernames, identifiers, search terms), then the composed and decomposed forms of “é” must be the same string. Normalization is essential here.
- Fairer counts. NFC makes a decomposed “é” count as one code point instead of two. But it only helps where a precomposed form exists; Devanagari conjuncts, flags, and emoji sequences still count as more than one. This is a real but modest benefit, and it matters most when the count is shown to the user.
Note what’s not on that list: consistency of limit checks across layers. Every layer needs to count the same form, but raw, unnormalized input is a form too (provided nothing in between normalizes it7), and it’s the one whose code point count can’t drift between Unicode versions (see “Unicode versions”, below). So for a string that’s only displayed, never compared, and limited for safety rather than shown as a count, normalization buys little and adds processing (and, in some languages, like Dart, a dependency).
Counting by Unicode/UTF-32 code points means that everything in the Basic Multilingual Plane and many emoji get a count of 1. That’s an improvement over UTF-16 (and UTF-8). It also doesn’t suffer from the interpretative counting of grapheme clusters.
But…
It still suffers from many of the problems mentioned above:
It can still count by more than one. Multi-code point grapheme clusters are not uncommon for some scripts (such as Devanagari, used by more than a billion people) and some emoji (such as all country flags).
Input limiting by code point in a way that isn’t grapheme-cluster-aware might truncate characters – causing them to be nonsense or otherwise confusingly incorrect. This isn’t hypothetical! I found that React Native on Android (but not iOS) does exactly this.
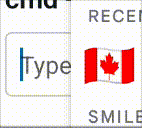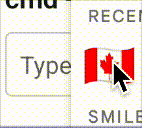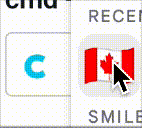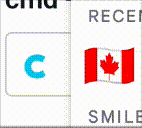
(The Canada flag emoji is a cluster made of a “Regional Indicator Symbol Letter C” followed by a “Regional Indicator Symbol Letter A”, but the length limit is truncating after the “C”.)
Normalization (NFC) is needed so that clusters with a precomposed form count as one code point, possibly per-keypress in the UI. Not a big deal, but extra complication and processing.
Even with those caveats, I think counting by Unicode code points is the sanest choice.
#### Hybrid counting
If we were inventing the best possible counting method, what would it look like?
Probably: Grapheme clusters without the unbounded risk.
We would want:
- a count of 1 for each “character” – even multi-code-point grapheme clusters in scripts like Devanagari
- a count of 1 for each emoji – even multi-code-point compounds
- a count of more than 1 for technically-a-single-grapheme Zalgo explosions
I think it would be reasonable to do that with logic like:
- Iterate through grapheme clusters:
- Are there N or fewer code points in the cluster? It counts as 1.
- Otherwise, it counts as 1 plus the number of code points above N.
What should N be? (Following answer mostly based on this informative StackOverflow post.)
The longest well-defined grapheme cluster I have found is 10 code points ("👨🏻❤️💋👨🏼" – “Kiss - Man: Medium-Light Skin Tone, Man: Medium-Light Skin Tone”). So maybe 10 should be our limit.
Unicode defines a Stream-Safe Text Format, which applies a limit of 30 (post NFKD normalization). “The value of 30 is chosen to be significantly beyond what is required for any linguistic or technical usage. While it would have been feasible to chose a smaller number, this value provides a very wide margin, yet is well within the buffer size limits of practical implementations.” So maybe 30 should be our limit.
(If I understand the Stream-Safe Text Process correctly, it provides a decomposition algorithm that is similar to what I suggested above. However, it would be more generous: a Zalgo character with 100 combining marks under my counting system would get a length of “72” (if N=30); under the Stream-Safe Text Process, it would have a length of “4”. I’m inclined to be less generous, but either approach still provides a bound, which is what we want.)
For a real-world example of capping marks within a cluster: in my testing (November 2026), Discord keeps at most 5 consecutive nonspacing marks (Unicode General Category Mn) and silently drops the rest when a message is sent. An enclosing mark (category Me), like U+0489, restarts the count, and marks outside the main Combining Diacritical Marks block count too. That’s the same idea as the Stream-Safe Text Format, but much more aggressive (5 rather than 30), and it strips rather than counts. It’s also a small instance of the inconsistency problem: the compose box shows the full text right up until you press Enter, and only then does the message lose its marks. Enclosing marks weren’t limited at all: 50 in a row came through on one letter. So Discord doesn’t bound the size of a cluster; it seems aimed at the marks that stack up, which are what make Zalgo text a nuisance. (Thanks to reader Fazal Singh Bhinder, whose study of Zalgo text in chat apps prompted these tests.)
Even if I think this kind of approach is optimal, I don’t think it’s perfect.
The byte size allowed would need to be about 100x the length limit. That’s… kind of a lot? (My gut feeling is equivocal.)
Many of the problems mentioned above with using grapheme clusters also apply here, including Unicode version concerns.
It’s very hard to recommend such a non-standard method of counting for anything that’s intended to be consumed externally (e.g., APIs), as it will cause a lot of confusion. Even internally, standardizing that between frontend, backend, and DB would carry a lot of bug risk. So, it would be more feasible if there were a common standard to refer to, code to, and consume, allowing for consistency in understanding and implementation.
With a snappy name. Maybe “graph length”.
In the Appendix, I include some implementations of this algorithm.
##### Twitter counting
Twitter uses an interesting hybrid counting method (docs, code (Apache licensed)). Here are some examples (using twttr.txt.getTweetLength()):
- “a”: 1
- “ӑ”: 1
- “字”: 2
- “🔤”: 2
- “👨👩👧👦”: 2
- “र्स्प”: 5
- “x̴͙̹̬̑̓͝͝”: 9
I won’t repeat the docs or logic, but generally:
- Many letters and punctuation get a count of 1
- Chinese, Japanese, Korean glyphs get a count of 2
- All valid emoji (even clusters) get a count of 2
- All other code points get a count of 2 each
NFC Unicode normalization is performed before any counting. The API requires UTF-8 encoding.
(Strange: The doc says that “Ồ” (U+1ED2) should have a count of 1, but I get 2.)
I like that there’s mostly an intuitive rule that’s like, “simple characters get a 1-count; complex characters get a 2-count”. Except:
- My use of “simple” sure is Euro-centric
- The rule doesn’t apply to more than a billion people (Hindi writers, etc.)
## Other considerations
There remain important questions and problems that are outside the scope of this post, but I’ll mention them here so you can keep them in mind.
### What to do when the limit is hit
This post is primarily about how to do the counting to determine if a limit has been hit, but also important is the question “and then what?” We’ll look at the two main categories of possible reactions and their frontend/backend concerns.
#### Reject
The simplest response to too-long input is just to reject it. You’re not manipulating the string to “fix” it, maybe you’re not even telling the user how much they’re over the limit, you just say “nope, too long”.
This is very common in backend code – an HTTP server will probably reply with 400. Maybe you’ll want to indicate which field was too long, maybe not. (You’ll definitely want to do request-size-sanity-limiting before you start considering individual fields.)
In the frontend, “rejecting” input might take the form of allowing the user to enter too much data into a field, detecting that it’s too long, displaying an error message and disabling form submission.
#### Truncate
In the frontend, this might take the form of halting further input into a field or it might mean actively truncating input before submitting. In the backend, it will mean actively truncating. Either form has the risk of breaking characters.
Unicode code points can be broken if we’re limiting by UTF-8 or UTF-16 and we truncate in the middle of a code unit sequence. We’ll end up with an invalid encoding sequence.
Grapheme clusters can be broken if we’re limiting by UTF-8, UTF-16, or Unicode code points and we truncate in the middle of a cluster sequence. We can end up with distorted or different characters or emoji.
So, truncating must be done in a sequence-aware manner. If the limit is hit in the middle of a code point or cluster sequence, you’ll need to back off until you find a boundary and do the truncating there. (Or, better yet, find some battle-tested library to do it for you.)
Truncate the same form of the string that you counted, and store that form. If you count the NFC-normalized string but then truncate or store the raw input, the truncation point you computed won’t line up with the raw string, and what you store can be longer than what you counted.
And then do a bunch of testing to make sure it works the way it should. (Note the React Native bugs mentioned elsewhere.)
Discussion about the relative UX merits of rejection versus truncation is interesting, but beyond our scope. (See this appendix for a concrete case where truncating is clearly better.)
[This section was prompted by an HN comment from aidenn0.]
### Unicode versions
There have been 16 major versions of the Unicode specification. Older Unicode text is compatible with newer Unicode versions, but the reverse is not necessarily true. For example, new versions may:
- Add new emoji and other characters (code points)
- Add new valid grapheme clusters, including multi-code-point emoji
- Update grapheme cluster segmentation rules
- Add character normalization rules
Possible problems that could be introduced include:
- If counting by grapheme clusters, there could be a mismatch between frontend and backend, causing them to disagree about whether a string is valid.
- Normalization could be different between frontend and backend, introducing the possibility of string length counting differences.
- A valid emoji entered on one client may not be valid on other clients with older system Unicode versions.
- If there are two different backends with different Unicode versions, they may not normalize a username the same way, resulting in one of them being unable to look it up. (Similarly for passwords, pre-hashing. Or any other string matching.)
- If strings are normalized and hashed (e.g., for signing or HMAC) in one place, and then the raw string is sent somewhere else for verification, the normalization step may not produce the same string, resulting in a different hash. (So don’t try to modify the input before checking. For example, the JSON Canonicalization Scheme specifies that “Although the Unicode standard offers the possibility of rearranging certain character sequences, referred to as “Unicode Normalization”, JCS-compliant string processing does not take this into consideration. That is, all components involved in a scheme depending on JCS MUST preserve Unicode string data “as is”.”)
And so on.
Where the Unicode data comes from matters too. Some implementations use the operating system’s Unicode data (like the glibc and ICU examples below), so behaviour can change with the device or server. Others bundle their own: Dart’s characters package ships its own tables (Unicode 16.0.0 as of version 1.4.0), so grapheme segmentation is fixed by the app build rather than the OS. That’s consistent across devices running the same build, but it won’t necessarily match your backend.
For a real-life story of this kind of version mismatch, search for “operating system-provided ICU” here. It also links to a scary discussion (HN discussion) about Unicode version differences in glibc causing PostgreSQL index corruption when the same data is used on a different server machine. “No surprise; I have been expecting to hear about such breakage, and am surprised we hear about it so rarely. We really have no way of testing for breakage either. :-(” Yikes.
“Did Postgres Lose My Data?” is another good dive into Unicode collation (sorting) changes. The author did an analysis of actual inter-version differences. (From the Unicode Technical Report #10: “Collation order is not fixed. Over time, collation order will vary: there may be fixes needed as more information becomes available about languages; there may be new government or industry standards for the language that require changes; and finally, new characters added to the Unicode Standard will interleave with the previously-defined ones. This means that collations must be carefully versioned.”)
I have never seen “Unicode version” be specified as a requirement in an API (or other) spec, but I think it should be, strictly speaking. Otherwise you can’t be certain that both sides understand strings in the same way.
On the other hand… This might be another case of being overly paranoid?
### Normalization concerns
It might be tempting to have your API require that strings be Unicode normalized before submission, because: a) you’re already normalizing on the frontend in order to count the length, and b) it’s your API and you make the rules. For most strings, I think it’s a bad idea.
You’re not going to trust the API-caller to actually do it, so you’ll have to normalize on the backend anyway, compare the result with the raw input, and reject the input if they differ. And that check can go wrong: if the client and server have different Unicode versions, and the string contains characters that only the newer one knows about, they can disagree about whether the string is normalized. The backend could end up refusing perfectly valid input. For most strings, it’s simpler to just normalize on receipt.
Identifiers are the exception. If the server normalizes an identifier on receipt, the identifier it stores can differ from the one the client sent, and the client is left holding a string that doesn’t match the server’s. Requiring NFC and rejecting anything else means that both sides hold exactly the same string. Better still is to avoid the problem: Google says identifiers “should limit inputs to ASCII characters, typically letters, numbers, hyphens, and underscores”, which “ensures that there are never accidental collisions due to normalization.” But for APIs that allow all valid Unicode characters in unique identifiers, Google requires the rejection approach: “the API must reject any inputs that are not in Normalization Form C.”
The Unicode version risk is narrower than it sounds. Unicode’s normalization stability policy guarantees that a string containing only characters assigned in a given Unicode version normalizes the same way in every later version. So disagreement is only possible for text containing characters newer than one side’s Unicode version – and new emoji aren’t affected, since normalization doesn’t change them. For identifiers, I think that’s an acceptable risk in exchange for both sides holding the same string.
Also, don’t assume normalization makes a string shorter. Usually NFC shortens a string or leaves it alone, but some characters are excluded from composition and get decomposed even under NFC: “क़” (U+0958, Devanagari Letter Qa) becomes U+0915 U+093C, two code points. NFKC can expand more: the ligature “ffi” becomes “ffi”. So a string that fits the limit before normalization can exceed it after, which matters if one layer counts the raw input and another counts the normalized form.
Note that normalization is not zero-cost, and may be significant on very large data. For example, Django had a recent possible DoS vulnerability due to slow normalization.
### Encoding errors
Another thing to learn about your programming languages of choice is how they handle bad UTF-8 or UTF-16 encodings, and how you’re going to handle that when it happens.
It seems common to replace broken sequences with the Unicode replacement character, U+FFFD. E.g., when Go’s json.Unmarshal encounters a bad UTF-8 code unit sequence, it silently replaces it with U+FFFD.
Should you detect invalid sequences? Treat them as bad input? Or just pass them through?
### Processing overhead
In many cases, accessing (or counting) character encodings other than the one used for natively storing your strings is an O(n) operation. That is, the string needs to be scanned through to answer questions like, “how many UTF-16 code units are in this UTF-8 string?”, “how many Unicode/UTF-32 code points in this UTF-16 string?”, “how many grapheme clusters?” – converting from the internal encoding to the target.
For most situations, with most string lengths, this isn’t a significant performance problem, but keep it in mind if you’re doing this inside a big loop, or with huge data, or in an HPC context.
Swift, for one, leaves “breadcrumbs” after the first conversion, to speed up subsequent non-UTF-8 string accesses. I don’t know about other languages, but I don’t think this is common.
## Additional reading
Henri Sivonen’s “It’s Not Wrong that “🤦🏼♂️”.length == 7” is great. It covers some of the same basics I mention here, but goes into different nerdy things. For example, it looks hard at the density of information relative to character count (and various encodings) in many, many different languages. This gets into the “fairness” of limiting different languages by the different encodings, which I didn’t really consider here. (It does this by analyzing the myriad translations of a single document: the Universal Declaration of Human Rights. Smart.)
Nikita Prokopov’s “The Absolute Minimum Every Software Developer Must Know About Unicode in 2023 (Still No Excuses!)” does what it says on the tin. If you feel you want another pass over this stuff after reading this whole post, go there. It also gets into locale-dependent differences in handling of the same code points, which is good to know and also troubling.
Jeremy Schneider’s “Did Postgres Lose My Data?” is a good story about and investigation into the effects of Unicode version changes. It also links to good resources.
## Conclusions
What prompted me to write this was when I realized that UTF-16 was the (unstated) encoding used for string length counting and limiting in a project I was reviewing. This felt wrong to me: variable number of code units; not first-class in some languages I cared about; kind of a weird in-between. I also didn’t like that the choice wasn’t intentional or aware – it was just whatever the framework used for maxLength under the hood.
When I tried to swoop in with some “senior dev has seen it all” shit… I realized that I didn’t have a solid suggestion with clear reasons. And that’s a good excuse to develop them in a blog post.
One surprising – to me – outcome of this research is that UTF-16 isn’t actually a bad choice: for most languages, most of the time, only one code unit is needed for a non-emoji character. And it’s not like using Unicode code points is a huge improvement, since it also counts by more than one for grapheme clusters.
I was hoping for a clear right choice, backed by solid reasons, and I didn’t find one.
That being said, I think that counting by Unicode code points (with normalization) is the best approach. Did I take 7,000 words to say “just do what Google suggests”? Yes, okay, maybe, but now I know – and you know! – why. And that’s important. Plus, we got to learn some interesting and somewhat bonkers stuff about things we take for granted every day.
I’ll add a TL;DR at the top with takeaway points.
##
Appendix: Implement Hybrid Counting ✨Graph Length✨
For fun, let’s see what implementations of the “hybrid counting” approach would look like.
JavaScript:
/**
 * Counts the number of grapheme clusters in a string, with a sanity limit on the number
 * of Unicode code points allowed in the cluster. After 10 code points in a single cluster,
 * the remaining code points in the cluster are counted as one each.
 * The limit is intended to distinguish legitimate grapheme clusters (as used in emoji
 * and human languages) from less-legitimate uses, like Zalgo text.
 *
 * @param {string} s  - the input string
 * @returns {number}  - the grapheme length
 */
function graphLength(s) {
  // A bit of research suggests that the locale argument is ignored for grapheme segmentation
  const seg = new Intl.Segmenter(undefined, { granularity: 'grapheme' });

  let total = 0;

  // Iterate through the grapheme clusters
  for (const { segment } of seg.segment(s)) {
    // Spread … turns the cluster string into an array of Unicode code points
    const n = [...segment].length;

    if (n <= 10) {
      // Short enough to count as one
      total += 1;
    } else {
      // Too long. The first 10 code points count as 1, and the rest each count as another 1
      total += 1 + (n - 10);
    }
  }

  return total;
}
Go (using a third-party segmentation package that seems like the de facto standard):
import (
	"unicode/utf8"
	"github.com/rivo/uniseg"
)

func GraphLength(s string) int {
	var total int
	graphemes := uniseg.NewGraphemes(s)
	for graphemes.Next() {
		cluster := graphemes.Str()
		n := utf8.RuneCountInString(cluster)

		if n <= 10 {
			total += 1
		} else {
			total += 1 + (n - 10)
		}
	}
	return total
}
Those don’t seem terribly hideous. I would consider using that code.
See the Hybrid Counting section for thoughts about using 10 as the count, versus 30.
Whatever your limit, you may wish to add a log when you exceed it. If it’s just Zalgo text, that’s fine, but if a new character enters into a common use, then you probably want to know about it and change your limit.
You probably want to NFC-normalize a string before getting its graph length.
## Appendix: A personal length-limiting example
Years ago I wrote some code that did length-limiting for account creation fields. It’s really beside the point of this post, but I thought it might be slightly interesting – at least to myself – to consider that design in light of what I’ve researched here.
This was a for a Go backend, with account creation done on a website and logins from native Android and iOS (and IE webview on Windows).
There were no length requirements in the spec, but there obviously couldn’t be unbounded input. I wanted to give lots of space for the username and especially the password, including flexible allowance of character types (PRECIS UsernameCasePreserved and OpaqueString). (Nothing about how the usernames would be used required plain ASCII.)
So I decided on these design points:
- Backend:
- Overall request size limited to 4 KB.
- Username limited to 200 UTF-8 bytes.
- Password limited to 800 UTF-8 bytes.
- Frontend:
- Username limited to 50 Unicode code points.
- Password limited to 200 Unicode code points.
It makes some sense that I used UTF-8 bytes on the backend, since size was what I was really concerned about. It makes some sense that Unicode code points were used on the frontend, since they’re a way to stay safely within the backend limit. I chose values that I thought were large enough that the vast majority of users wouldn’t hit them.
But you can immediately see a few problems.
I didn’t properly (or at all) consider grapheme clusters. For a Hindi-speaker/writer, that username length could be reduced to 10 characters. I think that’s below acceptability.
After learning about PostgreSQL collation issues due to Unicode version changes, I would think carefully before allowing non-ASCII characters in an indexed field (e.g., username).
There’s a mismatch between frontend and backend encoding used for limiting. This is somewhat mitigated by a few things:
- The limits are fairly generous. (…except for grapheme clusters.)
- There is only one client where accounts can be created.
- There is no frontend length limiting done when logging in – only when creating or modifying an account.
So a mundane user wouldn’t be able to get into a bad state. And if someone F12-removes the submit-button-disabled state on the frontend, they can create a username/password beyond 50/200 code points, but they will still be able to log in with them. So that’s okay-ish.
What’s less good is that a user with a too-long username won’t be able to edit their account – adding an email address, say – without changing the username, because the UI will flag the (unchanged) username as invalidly long. Sure, if you mess around in browser DevTools you get what you deserve, but it’s still a good example of unfortunate consequences due to inconsistency.
## Appendix: A length-limiting example across programs
Recently I applied this post’s advice to a real system, and it turned out to be a clean example of inconsistent counting: not between the layers of one architecture, but between programs, written by different teams, that exchange one string.
One app creates a sharing link, and another app imports it. The link carries a token containing an ID, which is what matters, and a display name, which is only a label shown to the user. Several programs create these tokens and two consume them, and each limited the name with whatever its platform offered:
| Program | Role | Name limit | Unit counted |
|---|---|---|---|
| Desktop app (Go), signed out | sender | none | – |
| Desktop app (Go) signed in; mobile and web app (React Native) | sender | 3 to 32, PRECIS nickname rules, NFKC-normalized | Unicode code points |
| Command-line tool (Go) | sender | 1 to 32 | Unicode code points |
| Windows app (HTML UI) | sender | HTML maxlength="32" | UTF-16 code units |
| Newer client (Flutter) | receiver | 1 to 128 | UTF-16 code units (Dart String.length) |
| Older client (Java) | receiver | non-empty, no maximum | – |
Nobody chose UTF-16 code units for the newer client’s limit; it’s just what Dart’s String.length returns. And a name that broke the newer client’s rule didn’t fail gracefully: the whole token was rejected, discarding the perfectly good ID along with the label.
What the mismatches did:
- The one real failure: the signed-out desktop app could produce a name over 128 UTF-16 code units (129 ASCII characters, or 65 emoji), and the newer client rejected it, with an error message that didn’t mention the name. The limited senders could never hit it: 32 code points is at most 64 UTF-16 code units.
- The newer client’s limit allowed 128 characters from the Basic Multilingual Plane but only 64 emoji. Inconsistent, but unreachable from the limited senders.
- The Windows app allowed only 16 emoji where the code-point senders allowed 32. A mismatch between senders, but not a failure.
- The Windows app could also send an empty name, which both clients rejected. Not a length problem, but the same kind of uncoordinated validation.
The fix in the newer client treats the token as untrusted input, since the link can be opened from any web page or message:
- Bound the size before parsing anything. Reject a token longer than 4,096 characters before decoding it. (The token is base64url, so it’s ASCII, and every way of counting gives the same answer.) This is the request-size sanity limit from “Reject”, above. Rejecting is fine here, because no legitimate sender comes close.
- Never reject because of the name. The name is cosmetic; if it’s missing or empty, the client shows a generic label. Losing the ID over the label is the wrong trade.
- Clean the name, then count it. Control characters become spaces; bidirectional-text controls (which could reorder the surrounding UI text) and other invisible format characters are removed, except the zero-width joiner and non-joiner, which emoji sequences and Persian need; whitespace is collapsed and trimmed. Counting happens after cleaning, so the limit applies to the form that’s displayed.
- Count Unicode code points, with a limit of 32, matching the senders that have a limit, so every name they produce arrives unchanged.
- Don’t normalize. The name is only displayed, never compared with another system’s copy, and the count isn’t shown to anyone. That’s the case described under “Unicode code points”, above, where normalization buys little. (And Dart has no built-in normalization.)
- Truncate at grapheme cluster boundaries. Walk the grapheme clusters from the start, keeping each whole cluster while the code point count stays within the limit, and stop at the first one that doesn’t fit. Don’t skip it and continue with later clusters: that would remove characters from the middle of the name. If anything was cut, append “…”, which counts toward the limit. If not even the first cluster fits (Zalgo text, say), the name becomes empty.
Step 6 is a cheap, standards-friendly cousin of graph length: the limit is in code points, so Zalgo text is still bounded, but no emoji, flag, or Devanagari conjunct gets split.
The general lesson is TL;DR item 5 across teams rather than layers: several programs exchanged one string, each limited it with its platform’s default, and the strictest receiver turned a cosmetic field into a hard failure.
## LLM disclosure
The original post was entirely written by hand, with minimal LLM input. As of 2026-11-18, review and edits are happening with LLM assistance. I plan on coming up with a policy for LLM usage and writing on this blog, but… I haven’t done it yet.
I really don’t like publishing stuff I didn’t write myself but, at least this time, I think it’s important to make these updates to the post – and if I have to block of hours of time to do it, I don’t think it’ll get done. So, I’m going for maximum accuracy over purity of textual provenance… this time.
Hacker News discussion will be here, if any results.
When I make generalizations like this, please remember that I don’t actually know what I’m talking about. Maybe many languages consider something smaller than a character to be the atoms? For example, maybe for Japanese kanji it’s the radicals or even the strokes? I don’t know. This kind of glib generalization is just to give most readers a rough idea as we progress through concepts. ↩︎
After reading this post, Connor Taffe took a deep dive into the origins of “rune” (and UTF-8). Code archeology is cool. ↩︎
The overhead enables some cool properties of UTF-8, like: a) The first byte in a UTF-8 code unit sequence tells you how many bytes are in the complete sequence; b) if you look at any byte in a UTF-8 stream, you know if you’re at the start of a sequence or at a later position – handy if you want to back up or skip to the next sequence after an interruption. ↩︎
I don’t know most of these languages well or at all. Corrections welcome. ↩︎
I really like this explicit view approach, but I worry about the risks of defaulting to grapheme clusters. Someone should do a survey of Swift/Perl/Raku/Elixir projects to see how many are vulnerable to giant-grapheme-cluster attacks. ↩︎
I’m about to recommend Unicode normalization during validation, which is certainly also “additional processing and interpretation”. And converting between any encodings requires some kind of “interpretation”, but with varying complexity. ↩︎
Some layers normalize without being asked. Slack NFC-normalizes chat messages: in my testing (November 2026), a decomposed “é” was composed, out-of-order combining marks were reordered, and U+0958 was decomposed into U+0915 U+093C. Django’s user model NFKC-normalizes usernames during validation. The macOS HFS+ filesystem stores filenames “fully decomposed and in canonical order” (a variant of NFD), so a filename can come back in a different form than it was written in; APFS, its successor, stores names as given. Going the other way, Git on macOS has a
core.precomposeUnicodesetting that converts those decomposed filenames back to composed form. ↩︎